> ## Documentation Index
> Fetch the complete documentation index at: https://docs.getcollate.io/llms.txt
> Use this file to discover all available pages before exploring further.

# Cassandra Connector

> Connect Cassandra to Collate with our database connector. Step-by-step setup guide, configuration options, and metadata extraction for your NoSQL database.

export const ConnectorDetailsHeader = ({name, icon, stage, availableFeatures, unavailableFeatures = [], availableFeaturesCollate = []}) => {
  const showSubHeading = availableFeatures?.length > 0 || unavailableFeatures?.length > 0 || availableFeaturesCollate?.length > 0;
  const totalAvailableFeatures = [...availableFeatures || [], ...availableFeaturesCollate || []];
  return <div className="container">
      <div className="Heading">
        <div className="flex items-center gap-3">
          {icon && <div className="IconContainer">
              <img src={icon} alt={name} noZoom className="ConnectorIcon" />
            </div>}
          <h1 className="ConnectorName">{name}</h1>
          <span className={`StageBadge ${stage === 'PROD' ? 'prod' : 'beta'}`}>
            {stage}
          </span>
        </div>
      </div>
      {showSubHeading && <div className="SubHeading">
          <div className="FeaturesHeading">Feature List</div>
          <div className="FeaturesList">
            {totalAvailableFeatures.map(feature => <div className="FeatureTag AvailableFeature" key={feature}>
                ✓ {feature}
              </div>)}
            {unavailableFeatures.map(feature => <div className="FeatureTag UnavailableFeature" key={feature}>
                ✕ {feature}
              </div>)}
          </div>
        </div>}
    </div>;
};

<ConnectorDetailsHeader icon="/public/images/connectors/cassandra.webp" name="Cassandra" stage="BETA" availableFeatures={["Metadata"]} unavailableFeatures={["Query Usage", "Data Quality", "dbt", "Owners", "Lineage", "Column-level Lineage", "Tags", "Stored Procedures", "Data Profiler", "Auto-Classification"]} />

This section provides guides and references to use the Cassandra connector.
Configure and schedule Cassandra metadata workflows from the Collate UI:

* [Requirements](#requirements)
* [Metadata Ingestion](#metadata-ingestion)
* [Enable Security](#securing-cassandra-connection-with-ssl-in-collate)
* [Troubleshooting](/ai-2-0/connectors/database/cassandra/troubleshooting)

## Requirements

To extract metadata using the Cassandra connector, ensure the user in the connection has the following permissions:

* Read Permissions: The ability to query tables and perform data extraction.
* Schema Operations: Access to list and describe keyspaces and tables.

## Metadata Ingestion

To ingest metadata from Cassandra, you need to create a service connection. The service connects Cassandra with Collate. Once you create a service, Collate automatically starts ingesting metadata.

### Step 1: Add New Service

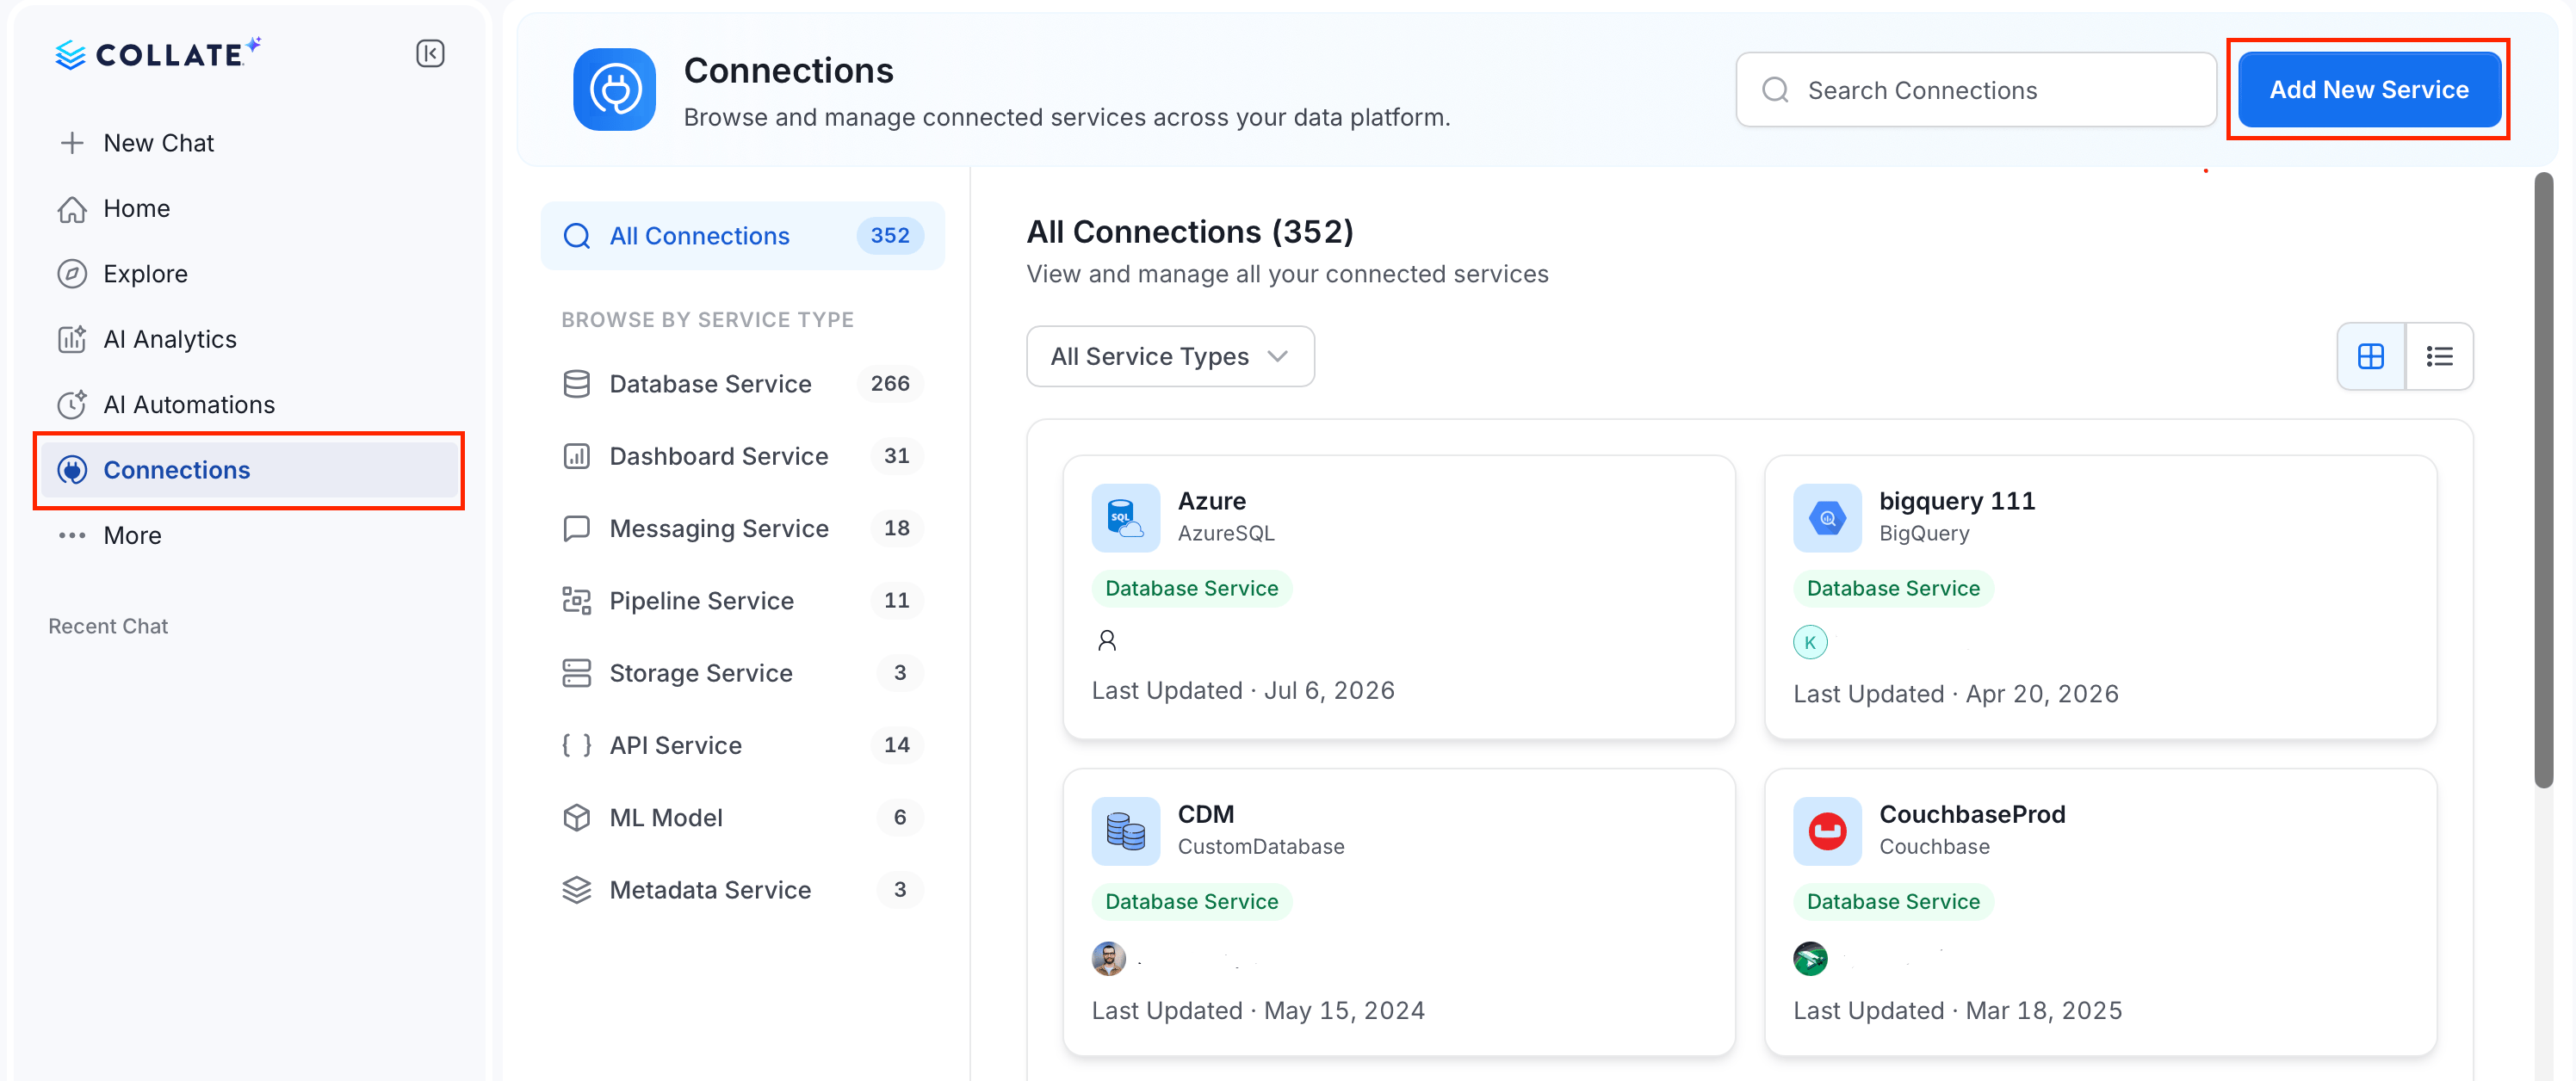
1. In the left navigation, click **Connections**.
2. On the **Connections** page, click **Add New Service**.

<img src="https://mintcdn.com/collatedocs/bv5oe4uRjuorTJO1/public/images/ai-2.0/connectors/metadata-ingestion/add-new-service.png?fit=max&auto=format&n=bv5oe4uRjuorTJO1&q=85&s=733cef1141ef13d318634aa9f407eb2b" alt="Add New Service" width="2992" height="1256" data-path="public/images/ai-2.0/connectors/metadata-ingestion/add-new-service.png" />

### Step 2: Select a Service and Connector

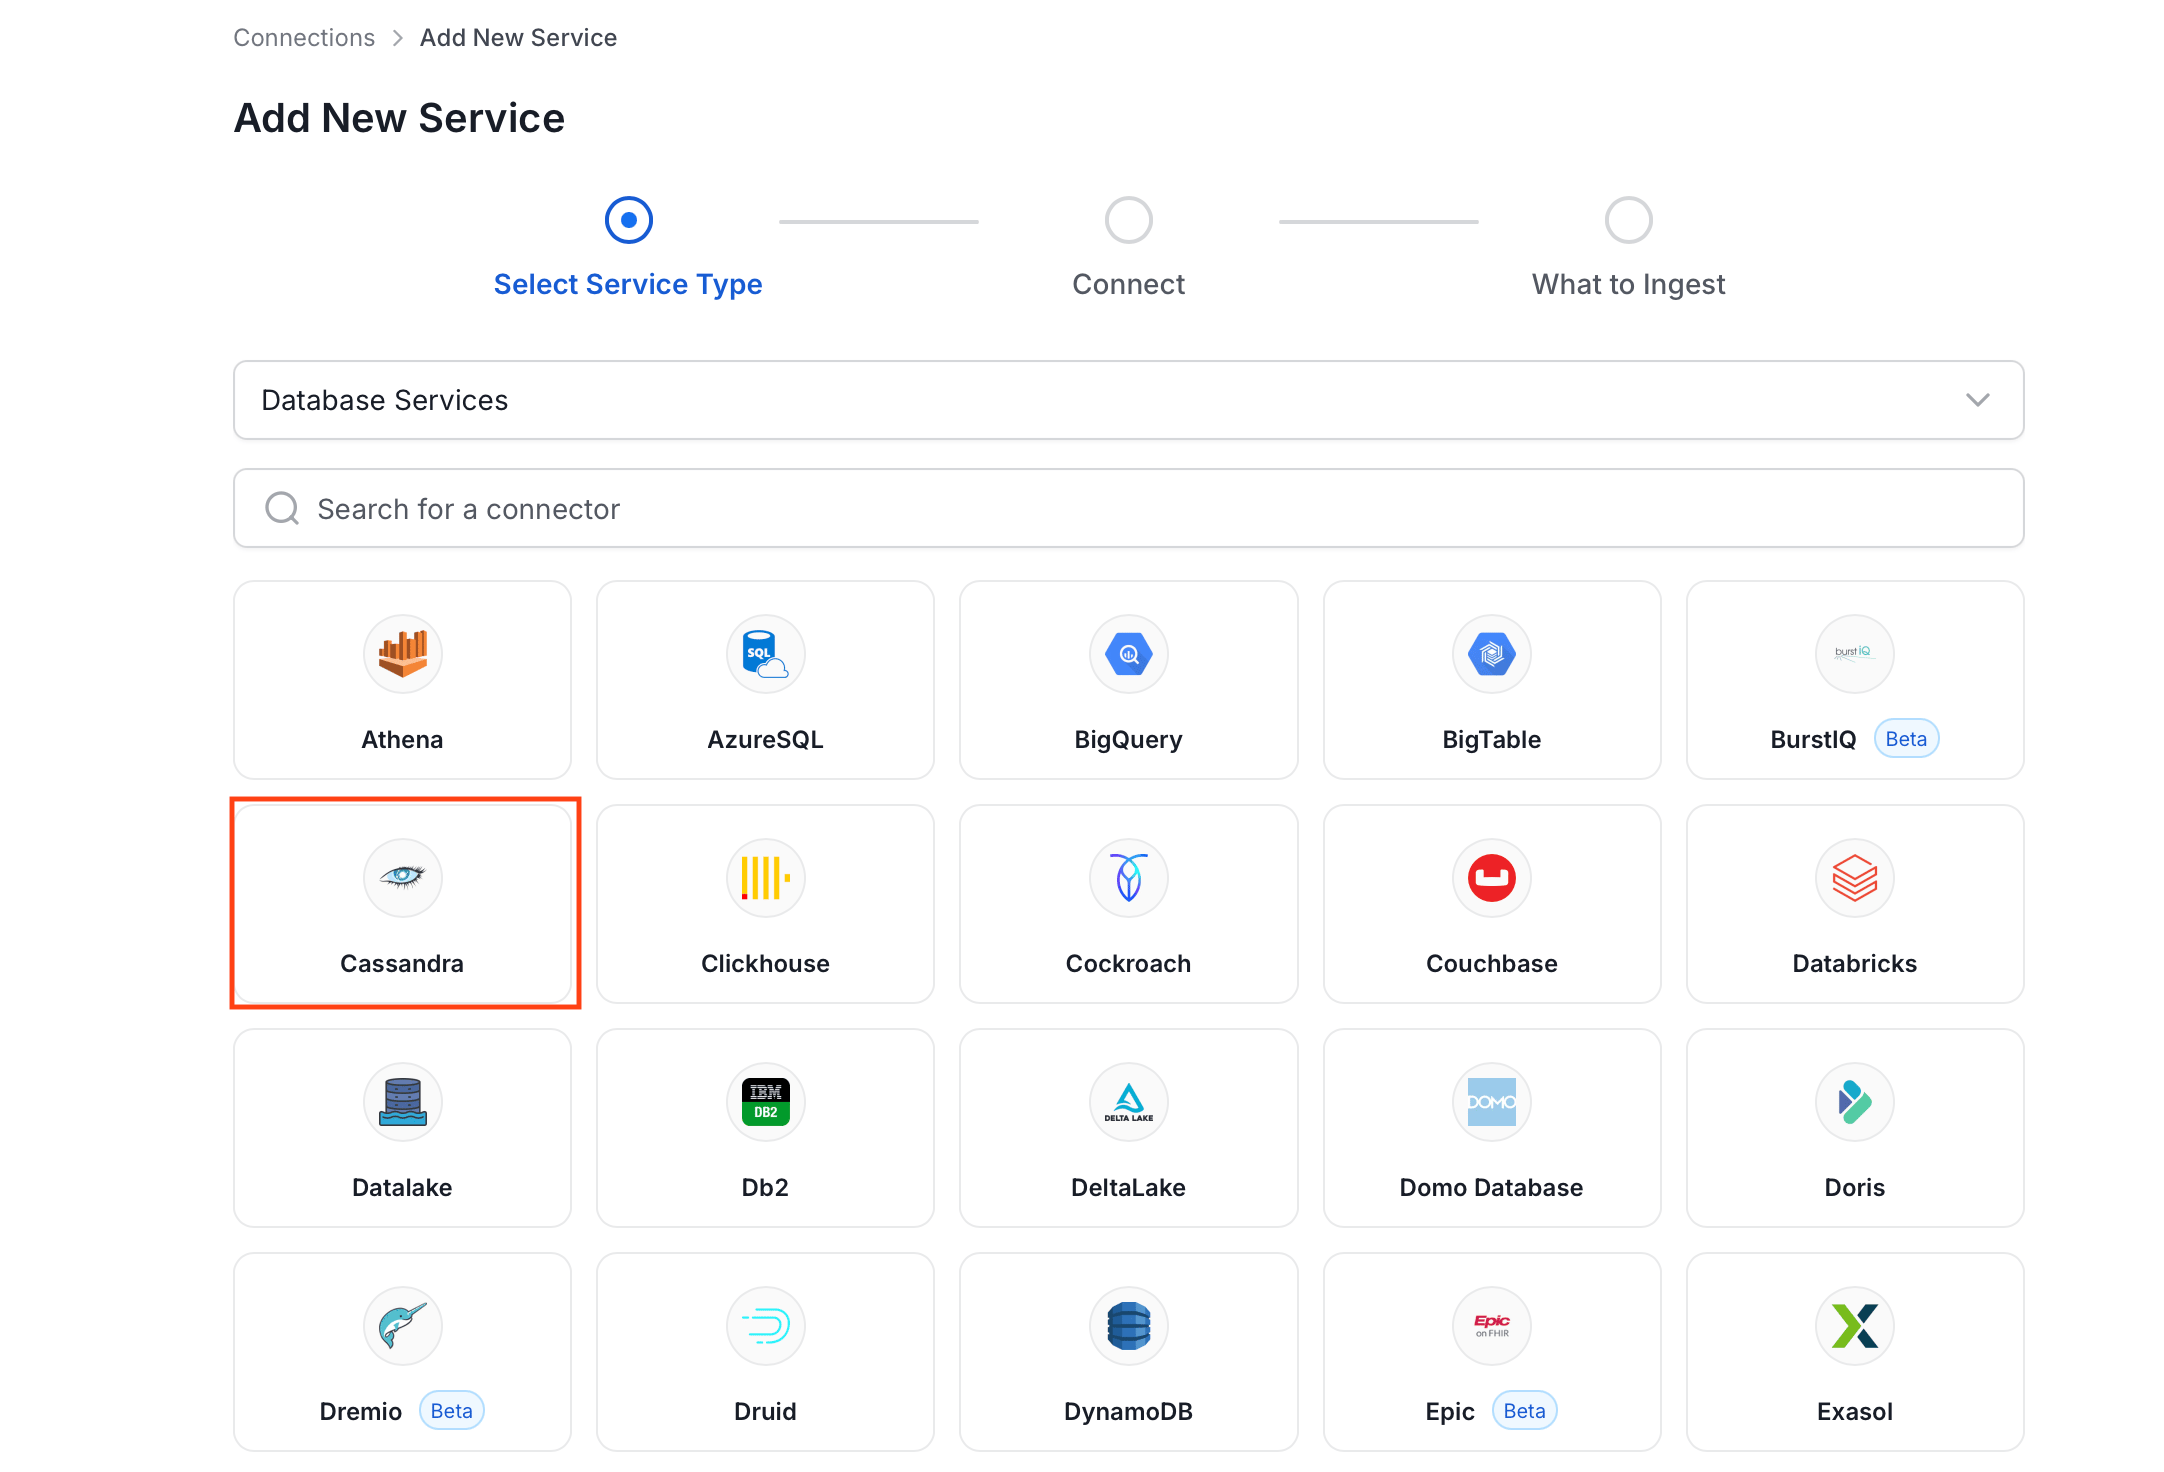
From the service type dropdown, select **Database Services**, then click the **Cassandra** connector tile.
<img src="https://mintcdn.com/collatedocs/kTp2dTyiNAX4Np5A/public/images/ai-2.0/connectors/metadata-ingestion/Database/select-service/cassandra.png?fit=max&auto=format&n=kTp2dTyiNAX4Np5A&q=85&s=b3bc76b0c33af54225962b6381e58f87" alt="Select Service" width="2164" height="1472" data-path="public/images/ai-2.0/connectors/metadata-ingestion/Database/select-service/cassandra.png" />

### Step 3: Add Service Name and Description

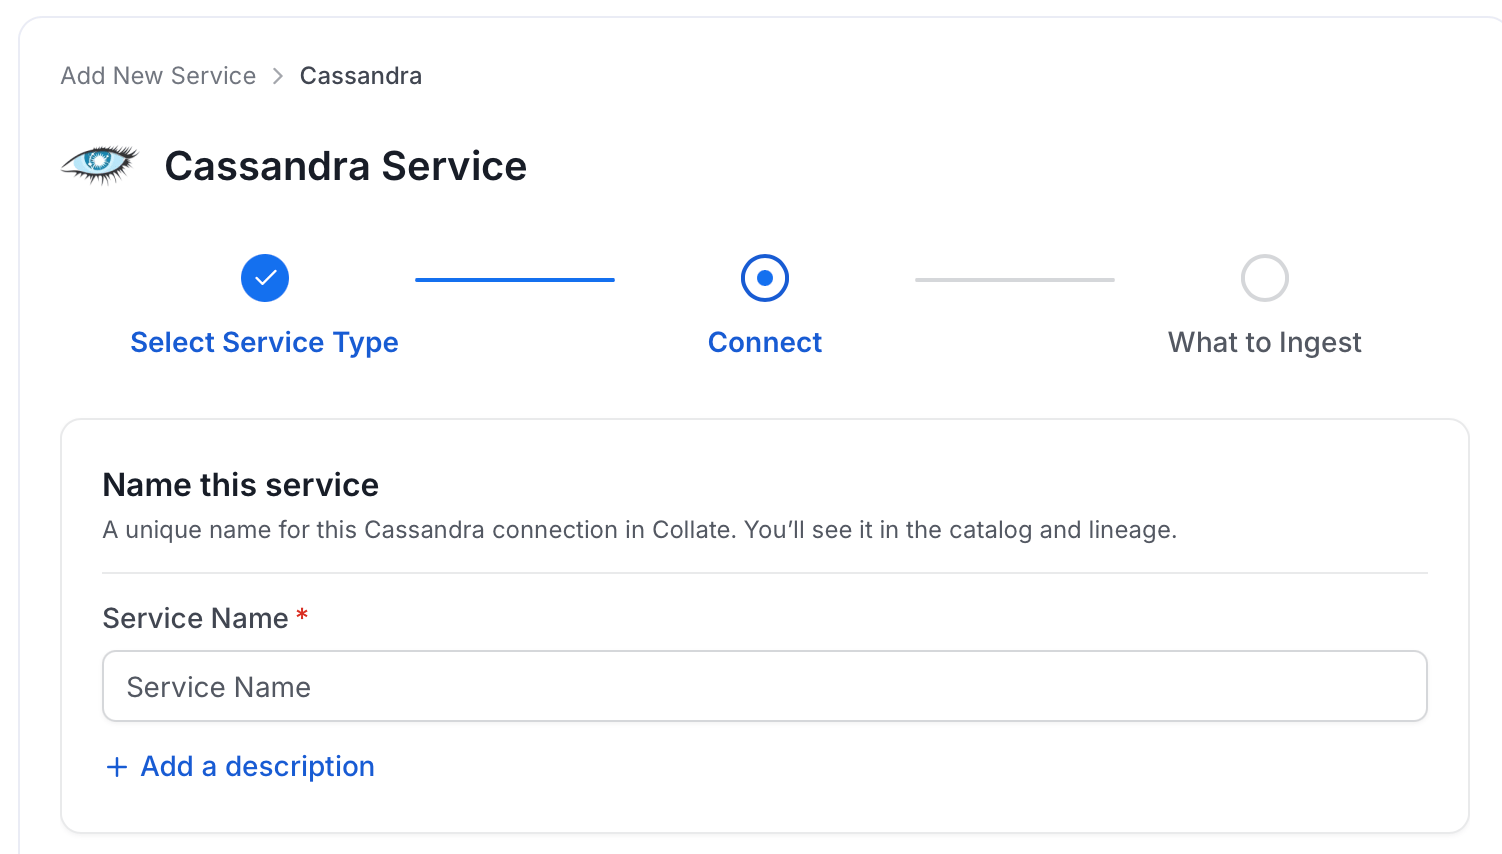
* Enter a unique, descriptive **Service Name**. Collate identifies services by their service name. Enter a name that distinguishes this deployment from other Cassandra services you are ingesting metadata from.
* Optional: Enter a **Description** for the service.
<img src="https://mintcdn.com/collatedocs/bWmb7UY94lEjxxg4/public/images/ai-2.0/connectors/metadata-ingestion/Database/service-name/cassandra.png?fit=max&auto=format&n=bWmb7UY94lEjxxg4&q=85&s=a9cbbfde3488d6affaa1f06758a39d8a" alt="Add New Service Name" width="1502" height="854" data-path="public/images/ai-2.0/connectors/metadata-ingestion/Database/service-name/cassandra.png" />

<Note>
  **Note**: The service name cannot be changed after it is set.
</Note>

### Step 4: Configure Connection Options

Specify where ingestion runs, provide your source credentials, and verify the connection.

#### Select Ingestion Runner

Select an **Ingestion Runner**: the runner where the ingestion pipeline will execute.

<img src="https://mintcdn.com/collatedocs/bv5oe4uRjuorTJO1/public/images/ai-2.0/connectors/metadata-ingestion/select-ingestion-runner.png?fit=max&auto=format&n=bv5oe4uRjuorTJO1&q=85&s=1249f828648614445e8a976ea1933487" alt="Add Name and Select Ingestion Runner" width="1444" height="506" data-path="public/images/ai-2.0/connectors/metadata-ingestion/select-ingestion-runner.png" />

#### Enter Connection Details

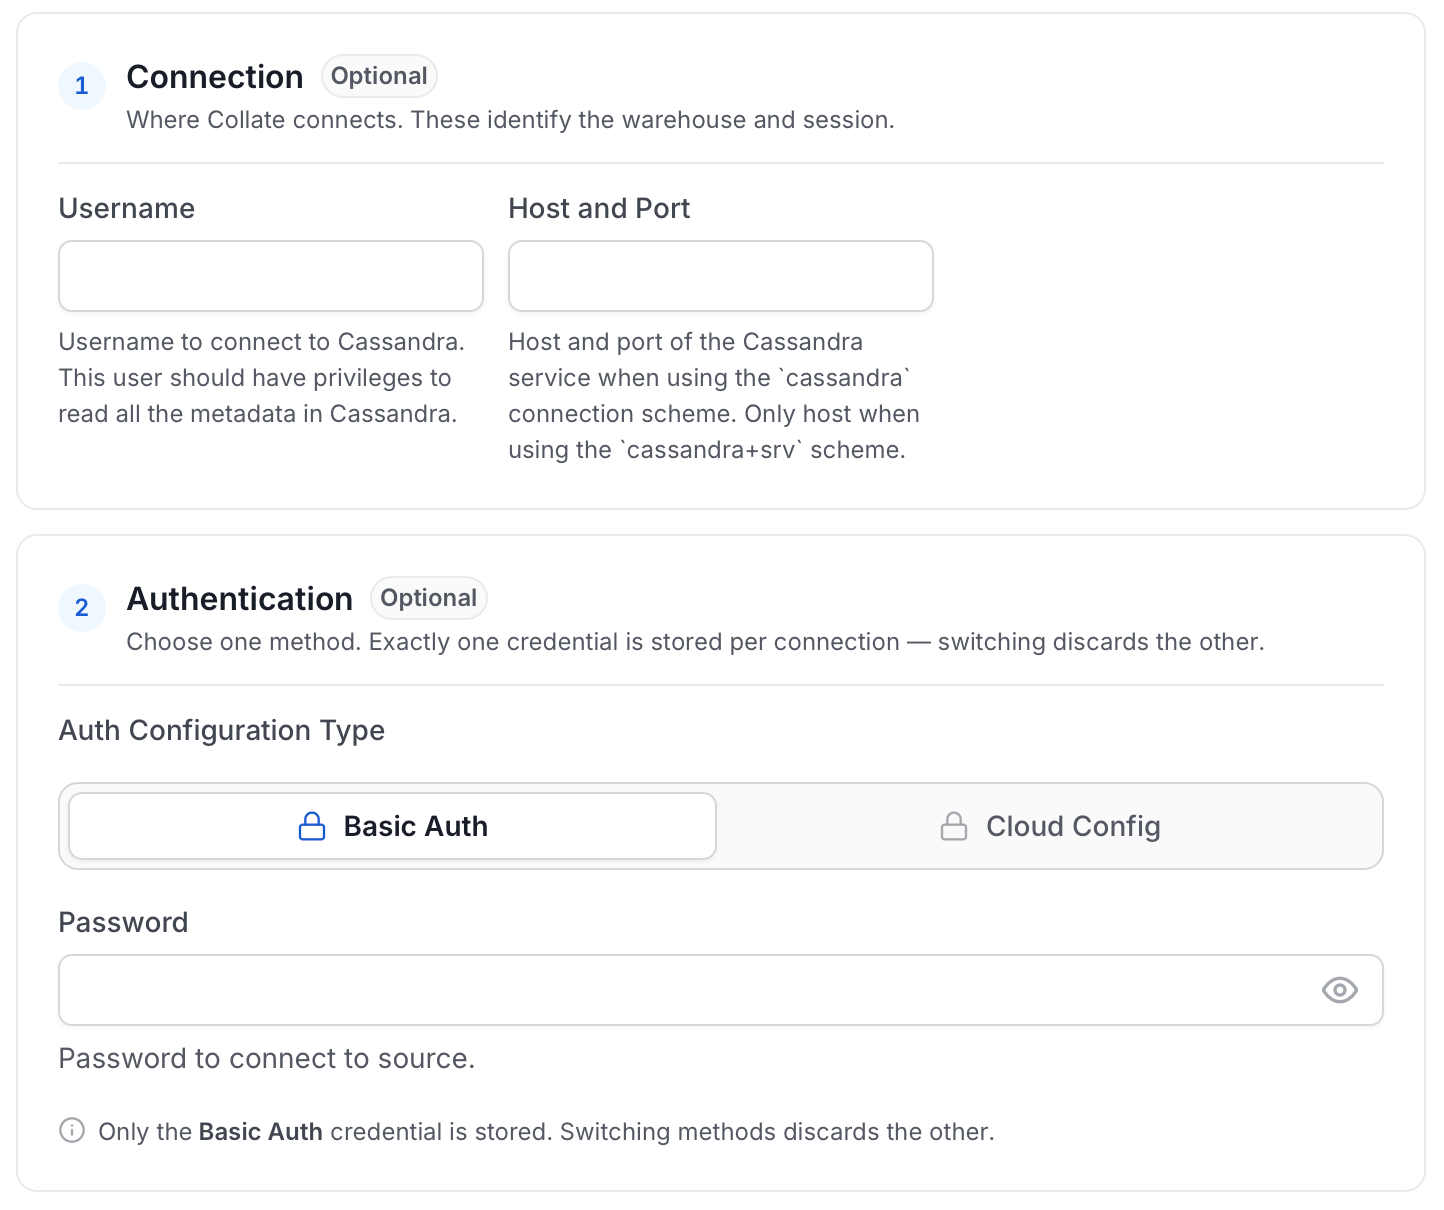
Enter the connection details for Cassandra. The right-hand panel in the UI displays inline help for each field.
<img src="https://mintcdn.com/collatedocs/kTp2dTyiNAX4Np5A/public/images/ai-2.0/connectors/metadata-ingestion/Database/connection-details/cassandra.png?fit=max&auto=format&n=kTp2dTyiNAX4Np5A&q=85&s=6456f54bb89e0f1a112a1e224c843bd5" alt="Configure Service Connection" width="1444" height="1210" data-path="public/images/ai-2.0/connectors/metadata-ingestion/Database/connection-details/cassandra.png" />

* **Username**: Username to connect to Cassandra. This user must have the necessary permissions to perform metadata extraction and table queries.
* **Host Port**: When using the `cassandra` connection schema, the hostPort parameter specifies the host and port of the Cassandra. This should be specified as a string in the format `hostname:port`, for example, `localhost:9042`.
* **databaseName**: Optional name to give to the database in Collate. If left blank, we will use the default database name.
* **Auth Type**: Following authentication types are supported:

1. **Basic Authentication**:
   We'll use the user credentials to connect to Cassandra

* **password**: Password of the user.

2. **DataStax Astra DB Configuration**:
   Configuration for connecting to DataStax Astra DB in the cloud.

* **connectTimeout**: Timeout in seconds for establishing new connections to Cassandra.
* **requestTimeout**: Timeout in seconds for individual Cassandra requests.
* **token**: The Astra DB application token used for authentication.
* **secureConnectBundle**: File path to the Secure Connect Bundle (.zip) used for a secure connection to DataStax Astra DB.

#### SSL Modes

There are a couple of types of SSL modes that Cassandra supports which can be added to ConnectionArguments, they are as follows:

* **disable**: SSL is disabled and the connection is not encrypted.
* **allow**: SSL is used if the server requires it.
* **prefer**: SSL is used if the server supports it.
* **require**: SSL is required.
* **verify-ca**: SSL must be used and the server certificate must be verified.
* **verify-full**: SSL must be used. The server certificate must be verified, and the server hostname must match the hostname attribute on the certificate.

#### SSL Configuration

In order to integrate SSL in the Metadata Ingestion Config, the user will have to add the SSL config under sslConfig which is placed in the source.

#### Test Connection

Once the credentials have been added, click on **Test Connection** and **Save** the changes.
<img src="https://mintcdn.com/collatedocs/bv5oe4uRjuorTJO1/public/images/ai-2.0/connectors/metadata-ingestion/test-connection.png?fit=max&auto=format&n=bv5oe4uRjuorTJO1&q=85&s=3365cff7bb9d82c85a2ff9ab559d6f11" alt="Test Connection" width="1446" height="188" data-path="public/images/ai-2.0/connectors/metadata-ingestion/test-connection.png" />

### Step 5: Configure Ingestion Options

In the **What to Ingest** step, use filter patterns to control which assets Collate ingests from your database service. Filter patterns use regular expressions applied to asset names.

#### How Filter Patterns Work

* **Include**: Add one or more comma-separated regular expressions. Collate ingests only assets whose names match at least one expression. Leave blank to include all assets.
* **Exclude**: Add one or more comma-separated regular expressions. Collate skips any asset whose name matches an expression. Leave blank to exclude nothing.

Rules match asset names using one of five expressions:

* **contains**: matches any name containing the value. For example, `sales` matches `my_sales_data` and `sales_2024`.
* **starts with**: matches names beginning with the value. For example, `prod_` matches `prod_db` and `prod_schema`.
* **ends with**: matches names ending with the value. For example, `_raw` matches `events_raw` and `logs_raw`.
* **is exactly**: matches the exact name only. For example, `analytics` matches only `analytics`.
* **matches regex**: matches names using a regular expression. For example, `^prod_.*_v\d+$` matches `prod_events_v1`.

When both Include and Exclude are set, Exclude takes priority.
<Tip>
  **Tip**: Leave all filter patterns empty to ingest all databases, schemas, and tables available in the source.
</Tip>

**Filter Options**

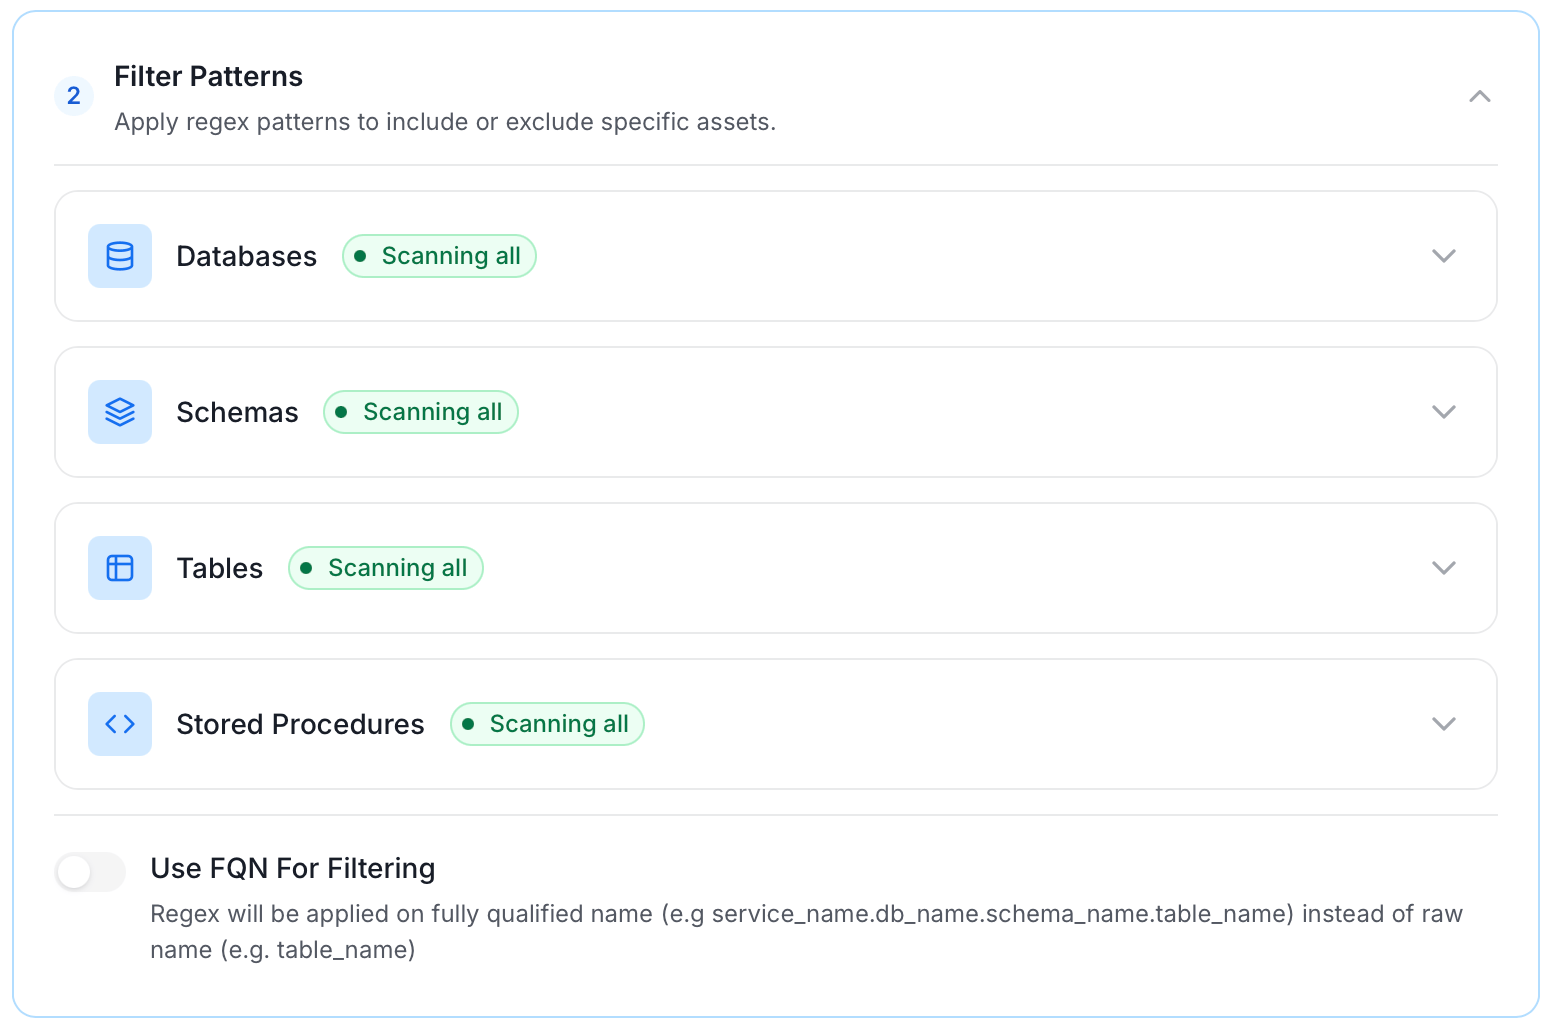
The Database, Schema, Table, and Stored Procedure sections each include the following filter options:

* **Database**: Controls which databases Collate ingests from the source.
* **Schema**: Controls which schemas within the ingested databases are included.
* **Table**: Controls which tables and views within the ingested schemas are included.
* **Stored Procedure**: Controls which stored procedures are included in metadata ingestion.

Each section provides the following controls:

* **Scan Mode**: You can choose between the following scan modes:
  * **Scan all**: Ingests every asset of that type the connector can access. This is the default.
  * **Only specific**: Enables include rules so only assets matching at least one rule are ingested.
* **Exclude system toggle**: Use this toggle to automatically filter out system-reserved names defined by the connector — for example, **Exclude system databases** for the Databases section.
* **Always exclude**: Add permanent exclusion rules (shown in red). Assets matching these rules are never ingested, regardless of include rules.
* **Preview**: Shows a real-time summary of what will be in scope based on your current rules.
* **Include rules** *(available only in **Only specific** mode)*: Click **+ Add** to define a rule. Added rules appear as chips; an asset is included if it matches any rule.

<Tip>
  **Tip**: If [AutoPilot](/ai-2-0/admin-guide/applications/autopilot) is enabled, usage tracking, data lineage, and other downstream workflows start automatically after the first metadata ingestion completes.
</Tip>

### Step 6: Create & Deploy

Click **Create & Deploy** to deploy the agent and start the first metadata ingestion run. Collate saves the service configuration and immediately begins pulling metadata from the source.

To monitor ingestion progress or view the service you just added, go to **Connections** in the left navigation and select your service.

## Configure Metadata Agent and Schedule Ingestion

The **Metadata Agent** extracts schemas, tables, columns, and other structural metadata from your source and keeps your Collate catalog in sync. It powers discovery, lineage, and governance across your data assets.

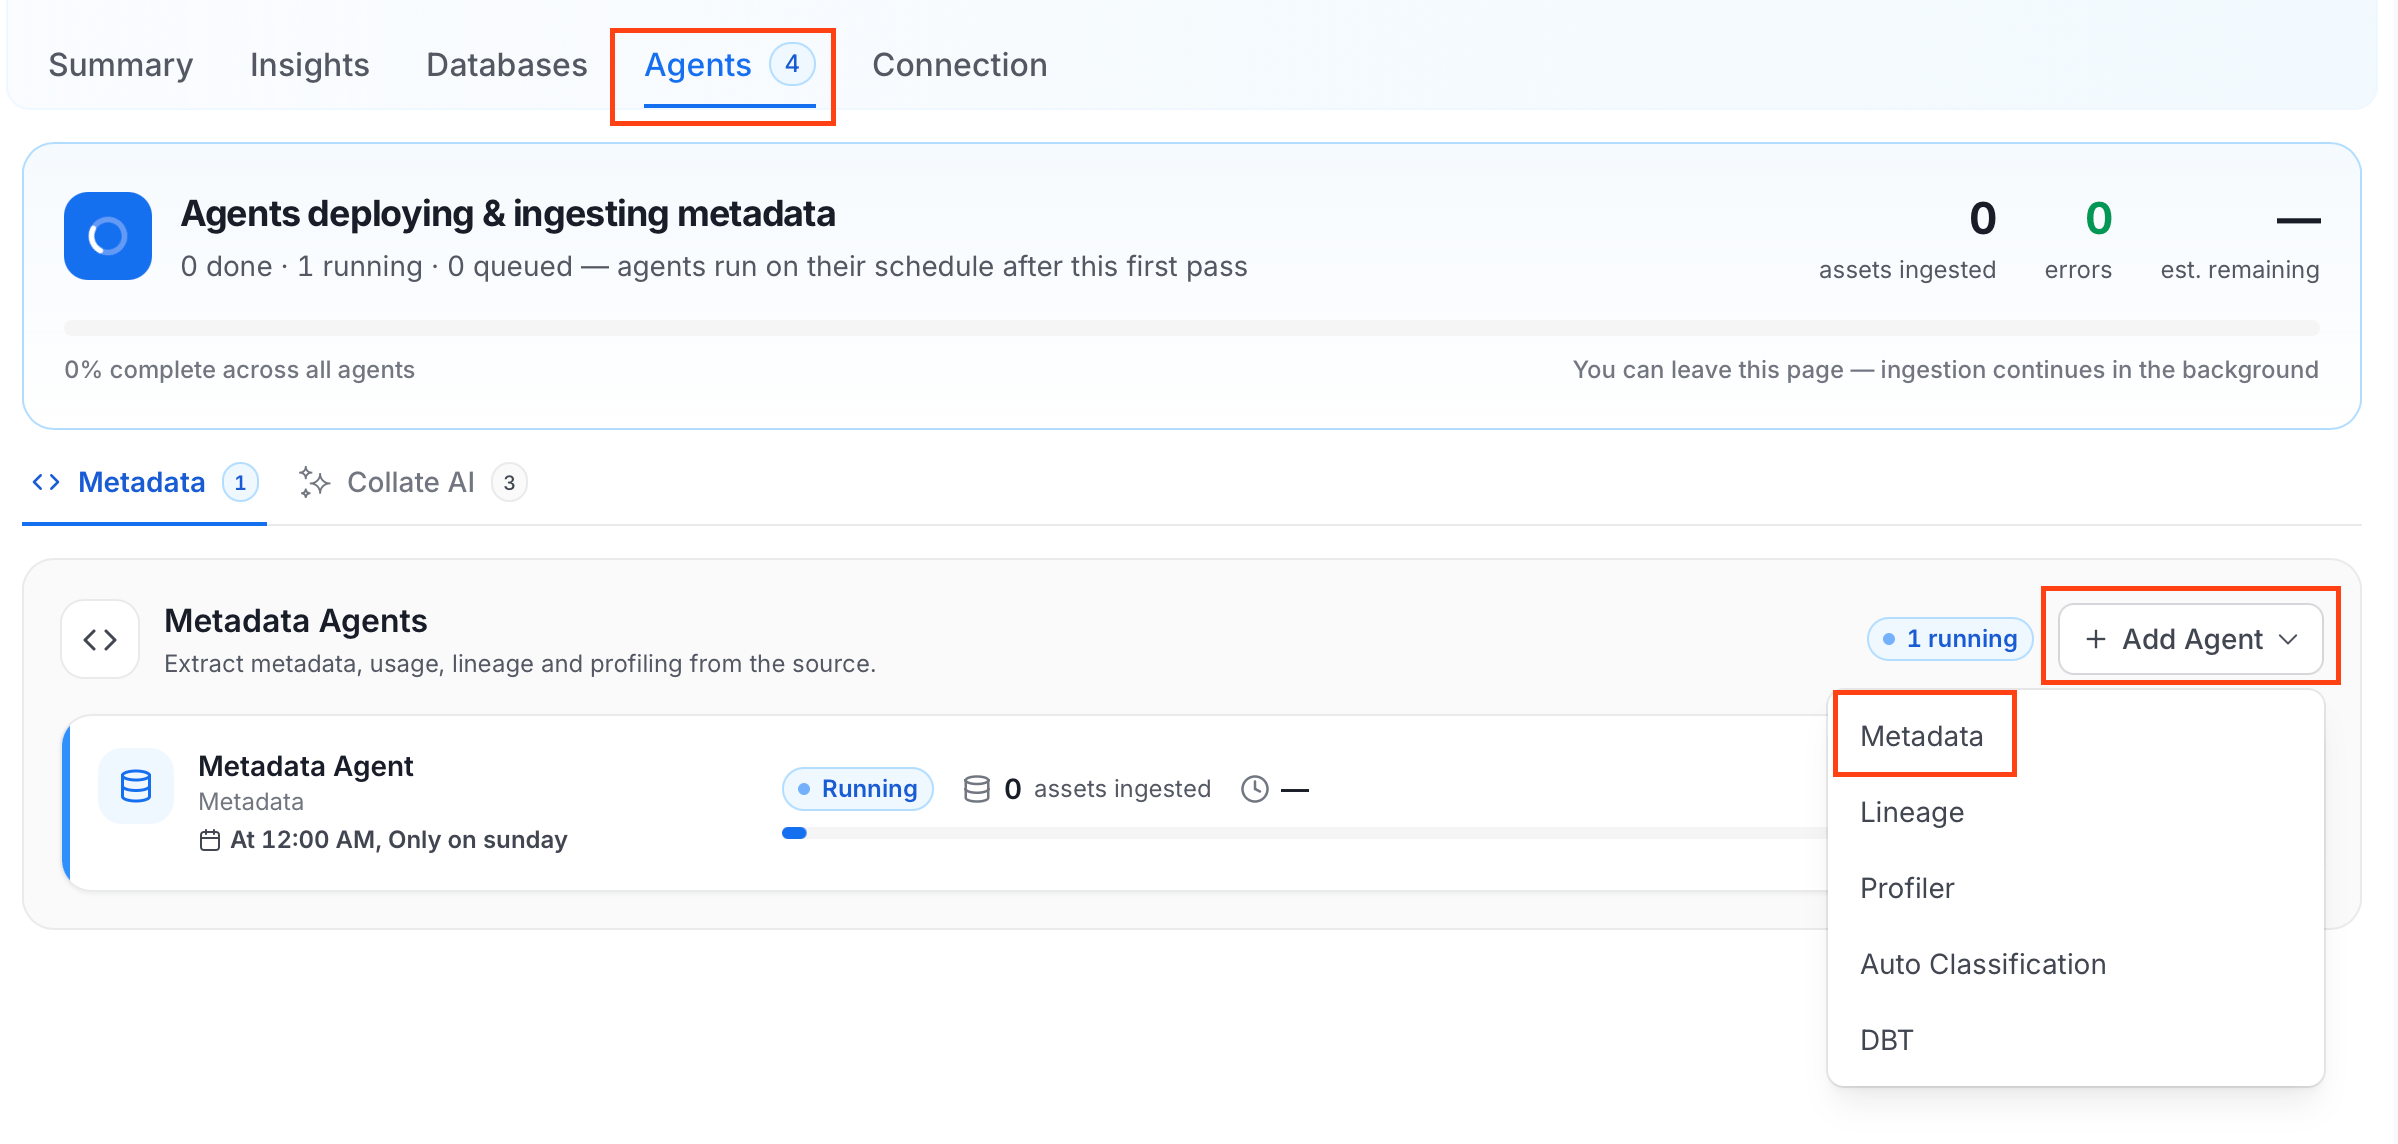
When you click **Create & Deploy**, Collate automatically deploys a Metadata Agent for this service and triggers the first ingestion run. View its status and run history from the **Agents** tab on the service detail page.

To configure the additional Metadata Agent and schedule ingestion, follow these steps:

1. In the left navigation, click **Connections** and select your service.

2. Click the **Agents** tab.

3. Click **Add Agent** and select **Metadata** from the dropdown.
   <img src="https://mintcdn.com/collatedocs/bv5oe4uRjuorTJO1/public/images/ai-2.0/connectors/metadata-ingestion/add-metadata-agent.png?fit=max&auto=format&n=bv5oe4uRjuorTJO1&q=85&s=accad7d1c4ddf209781bff851d51d464" alt="Add Metadata Agent" width="2398" height="1144" data-path="public/images/ai-2.0/connectors/metadata-ingestion/add-metadata-agent.png" />
   For some services, the dropdown is not available and clicking **Add Agent** takes you directly to the agent configuration page.

4. On the **Configure Ingestion** page, do the following and click **Next**.

   * **Name this Ingestion**: Enter a unique recognizable name for this ingestion pipeline.

     <img src="https://mintcdn.com/collatedocs/bv5oe4uRjuorTJO1/public/images/ai-2.0/connectors/metadata-ingestion/metadata-agent-name.png?fit=max&auto=format&n=bv5oe4uRjuorTJO1&q=85&s=d5ec1f0f3742cadab8cd54c602c97239" alt="Name this Ingestion" width="1578" height="644" data-path="public/images/ai-2.0/connectors/metadata-ingestion/metadata-agent-name.png" />

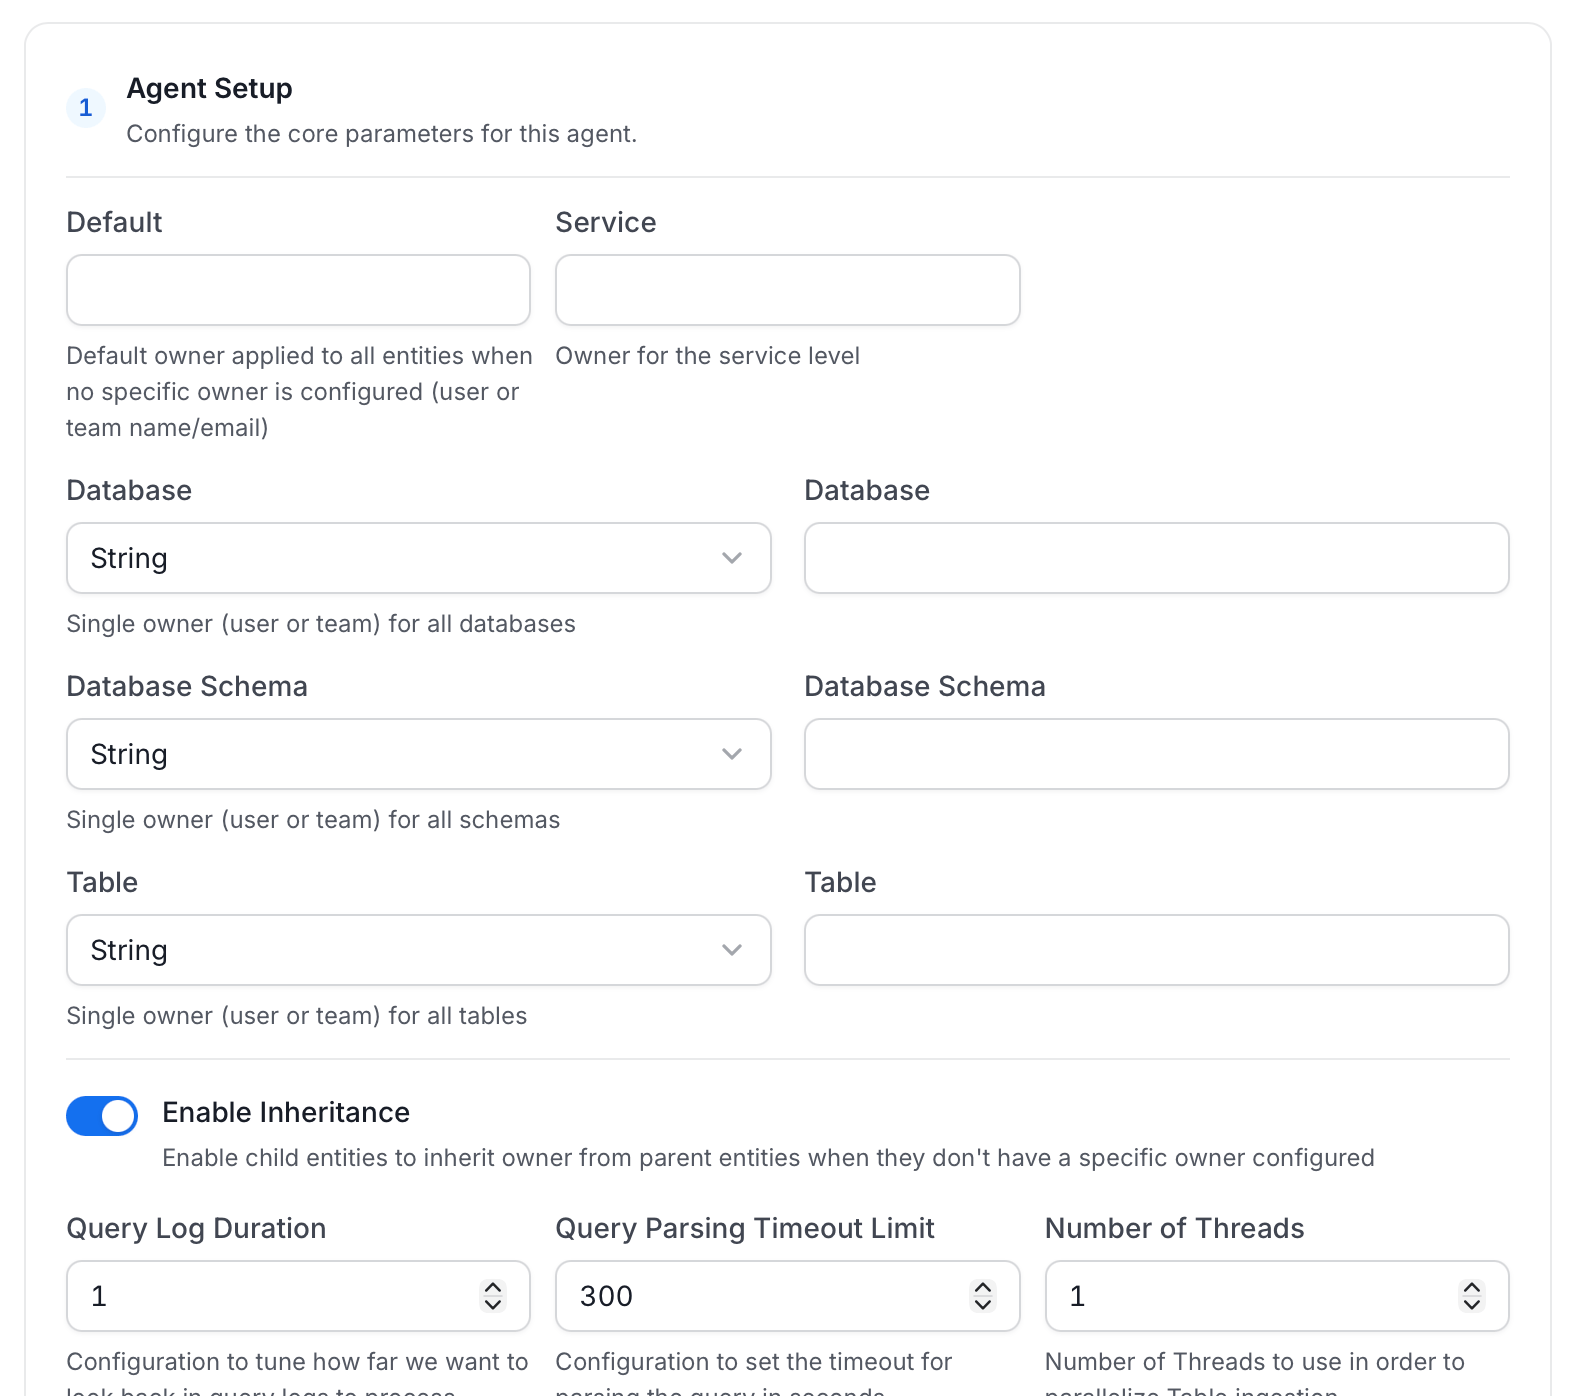
   * **Agent Setup**: Configure core parameters for metadata extraction. The following fields are available:

     | Field                                     | Default | Description                                                                                                                                                                                                                                                                                                         |
     | ----------------------------------------- | ------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
     | **Default Owner**                         | —       | Owner applied to any entity that has no owner from a more specific field below. Accepts a user or a team, by name or email.                                                                                                                                                                                         |
     | **Service Owner**                         | —       | Owner assigned to the service entity itself (the connector/service you're setting up, not the data inside it).                                                                                                                                                                                                      |
     | **Database Owner**                        | —       | Owner assigned to every database this agent ingests. Accepts either one owner for all of them, or a mapping of specific owners per database.                                                                                                                                                                        |
     | **Database Schema Owner**                 | —       | Owner assigned to every schema this agent ingests. Accepts either one owner for all of them, or a mapping of specific owners per schema.                                                                                                                                                                            |
     | **Table Owner**                           | —       | Owner assigned to every table this agent ingests. Accepts either one owner for all of them, or a mapping of specific owners per table.                                                                                                                                                                              |
     | **Enable Inheritance**                    | On      | When on, an entity with no owner of its own inherits one from the nearest parent that has one, checked in this order: table, then schema, then database, then service, then Default Owner. Turn off if you want only the owners set explicitly above to apply, with no fallback.                                    |
     | **Query Log Duration**                    | 1       | How many days of query logs to look back through when processing stored procedure results.                                                                                                                                                                                                                          |
     | **Query Parsing Timeout Limit**           | 300     | How many seconds to spend parsing a single query before giving up on it and moving to the next. Raise this if large or complex queries are being skipped.                                                                                                                                                           |
     | **Number of Threads**                     | 1       | How many tables to ingest in parallel. Raising this can speed up ingestion on databases with many tables, at the cost of more load on the source.                                                                                                                                                                   |
     | **Incremental Extraction**                | Off     | When on, a run extracts only entities that changed since the last successful run, instead of re-scanning everything every time. Faster on large, mostly-unchanged databases.                                                                                                                                        |
     | **Successful Pipeline Run Lookback Days** | 7       | Only used when Incremental Extraction is on. How many days back to search for a prior successful run to use as the starting point for "what changed since then."                                                                                                                                                    |
     | **Safety Margin Days**                    | 1       | Only used when Incremental Extraction is on. Extra days added before that starting point, as a buffer so changes that were still in flight when the last run finished aren't missed.                                                                                                                                |
     | **Extract JSON Schema**                   | Off     | Sample values in JSON columns to infer and ingest their schema, so the individual fields inside a JSON column are visible in Collate rather than just "JSON". Requires `SELECT` permission on the sampled tables; if that permission is missing, the JSON column is still ingested, just without a detailed schema. |
     | **JSON Schema Sample Size**               | 10      | Only used when Extract JSON Schema is on. Number of rows sampled per JSON column to infer its schema. A larger sample gives more accurate results but takes longer to run.                                                                                                                                          |

     For more information about how the Default Owner, Service Owner, Database Owner, Database Schema Owner, Table Owner, and Enable Inheritance fields resolve an owner, see [Hierarchical Owner Configuration](/ai-2-0/how-to-guides/guide-for-data-users/ingestion/workflows/metadata/hierarchical-owner-configuration).
     <img src="https://mintcdn.com/collatedocs/kTp2dTyiNAX4Np5A/public/images/ai-2.0/connectors/metadata-ingestion/Database/database-agent-setup.png?fit=max&auto=format&n=kTp2dTyiNAX4Np5A&q=85&s=429839e5b479082a6909dd2a7734513d" alt="Agent Setup" width="1570" height="1396" data-path="public/images/ai-2.0/connectors/metadata-ingestion/Database/database-agent-setup.png" />

   * **Filter Patterns**: Apply include or exclude rules to scope which databases, schemas, tables, and stored procedures this agent ingests. For more information about various filter options, see **Step 5: Configure Ingestion Options**.
     <img src="https://mintcdn.com/collatedocs/kTp2dTyiNAX4Np5A/public/images/ai-2.0/connectors/metadata-ingestion/Database/database-filter-pattern.png?fit=max&auto=format&n=kTp2dTyiNAX4Np5A&q=85&s=8a0c5fcc3475acf8acc94e6eecb55a11" alt="Filter Patterns" width="1560" height="1030" data-path="public/images/ai-2.0/connectors/metadata-ingestion/Database/database-filter-pattern.png" />

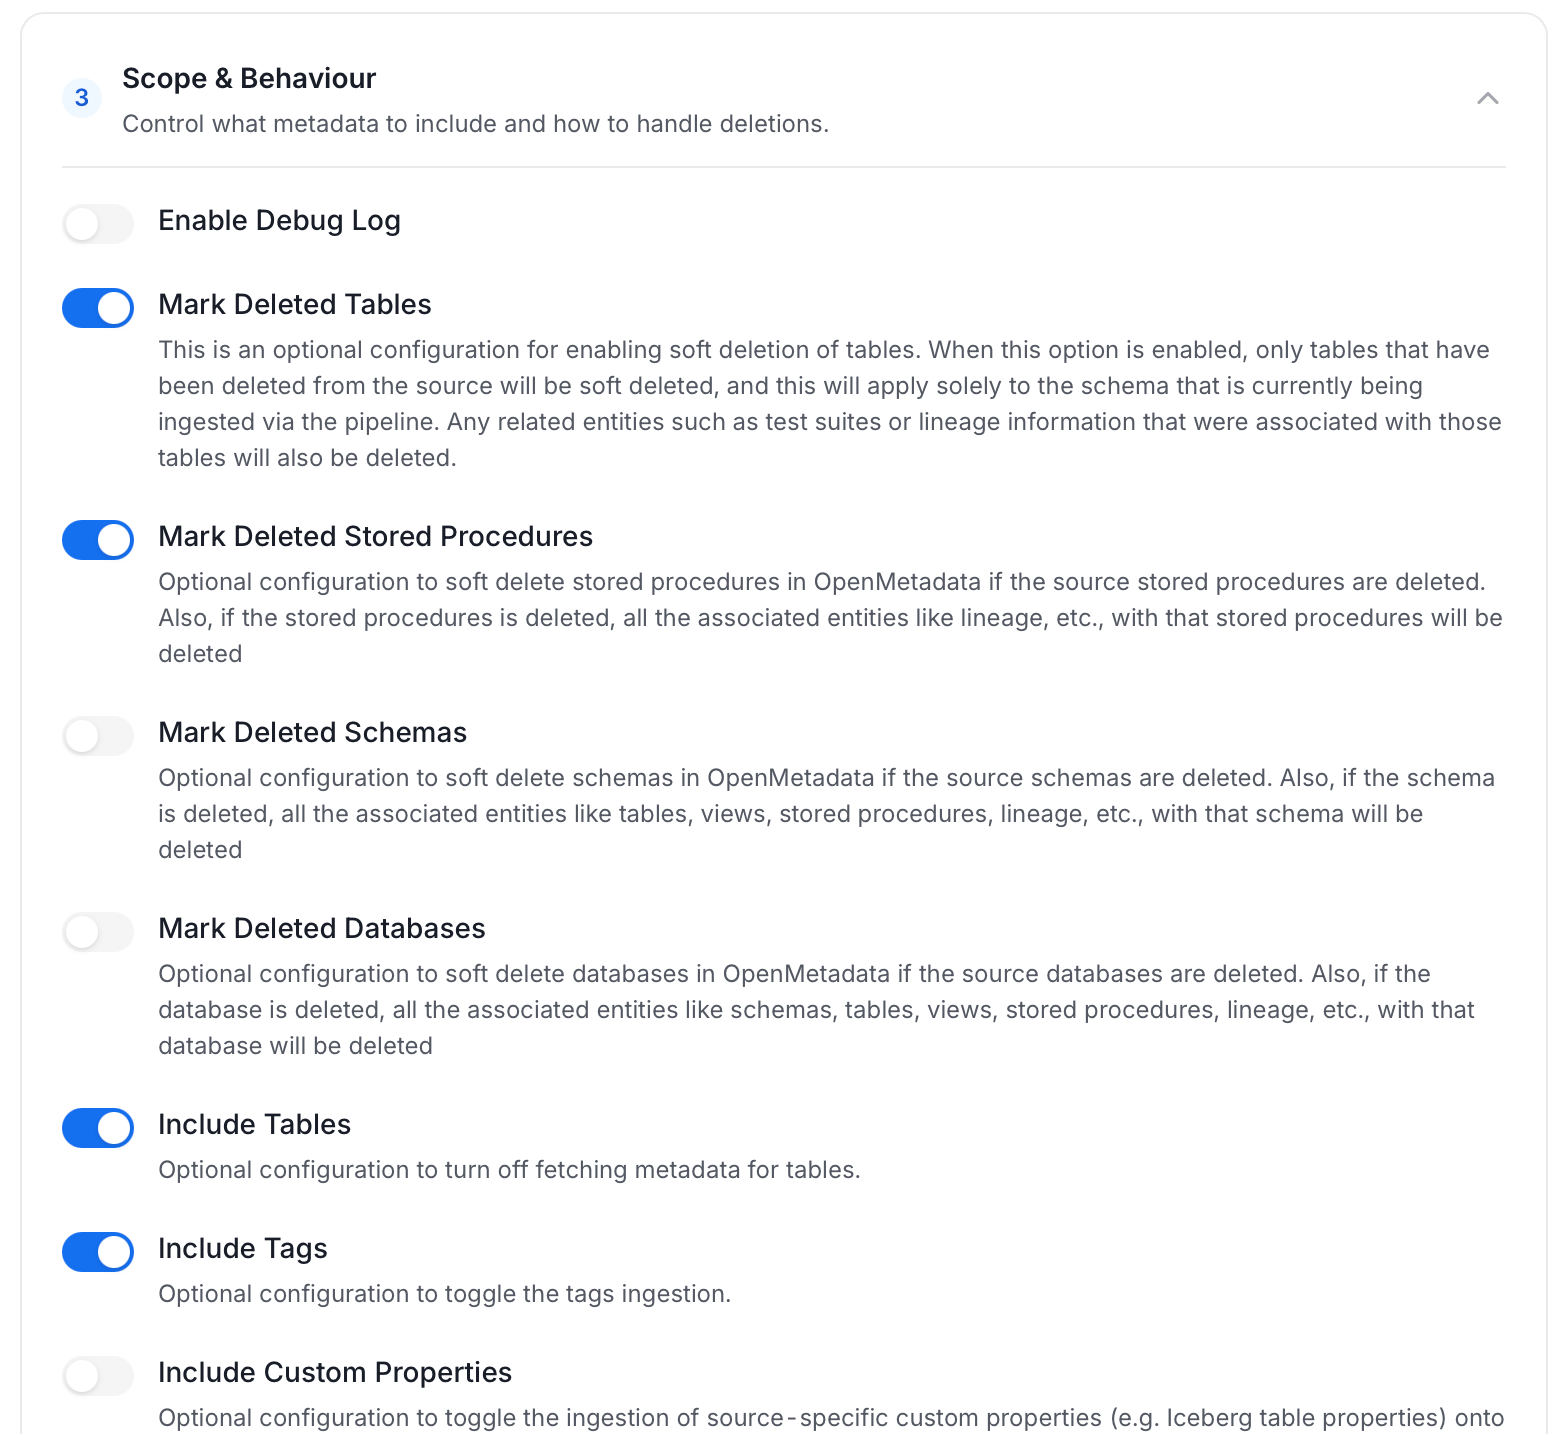
   * **Scope & Behaviour**: Control how the agent handles metadata during ingestion. Toggle each option on or off based on your needs:

     | Toggle                             | Default | Description                                                                                                                                                                                                                                             |
     | ---------------------------------- | ------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
     | **Include Tables**                 | On      | Ingest tables and their columns. Turn off to skip tables entirely, for example if this agent exists only to pull tags or stored procedures.                                                                                                             |
     | **Include Tags**                   | On      | Ingest tags already defined on tables/columns in the source system (for example, a classification tag applied in Snowflake) and bring them into Collate as tags on the same assets.                                                                     |
     | **Include Stored Procedures**      | On      | Ingest stored procedures as their own assets, so they show up in the catalog and can be linked into lineage.                                                                                                                                            |
     | **Include DDL Statements**         | Off     | Also ingest the raw `CREATE TABLE` / `CREATE VIEW` statement for each asset, so it's viewable in Collate alongside the asset's metadata.                                                                                                                |
     | **Include Owners**                 | Off     | When an ingested asset's owner in the source system is an email that matches an existing Collate user, assign that user as the asset's owner. Never overwrites an owner an asset already has in Collate.                                                |
     | **Include Custom Properties**      | Off     | Ingest source-specific metadata that doesn't map to a standard Collate field (for example, a database-specific attribute) into custom properties on the asset, if custom properties have been defined for that entity type.                             |
     | **Mark Deleted Tables**            | On      | If a table this agent previously ingested no longer exists in the source, soft-delete it in Collate too. Only affects tables within schemas this agent actually scans.                                                                                  |
     | **Mark Deleted Stored Procedures** | On      | Same as Mark Deleted Tables, but for stored procedures.                                                                                                                                                                                                 |
     | **Mark Deleted Schemas**           | Off     | If an entire schema this agent previously ingested no longer exists in the source, soft-delete the schema and everything in it.                                                                                                                         |
     | **Mark Deleted Databases**         | Off     | If an entire database this agent previously ingested no longer exists in the source, soft-delete the database and everything in it.                                                                                                                     |
     | **Override Metadata**              | Off     | On: values from the source (descriptions, tags, owners, display names) always overwrite what's currently in Collate, even if someone edited it there. Off: Collate only fills in fields that are still empty, so manual edits in Collate are preserved. |
     | **Enable Debug Log**               | Off     | Run this ingestion at DEBUG log verbosity instead of the normal level. Turn on when troubleshooting a failing or unexpected run; leave off otherwise, since debug logs are much larger.                                                                 |
     <Note>
       **Note**: Available toggles vary by connector. Stored procedure options only appear for connectors that support stored procedures.
     </Note>

     <img src="https://mintcdn.com/collatedocs/kTp2dTyiNAX4Np5A/public/images/ai-2.0/connectors/metadata-ingestion/Database/database-scope-behaviour.png?fit=max&auto=format&n=kTp2dTyiNAX4Np5A&q=85&s=6ada5b2870c990f494d1dac400e73459" alt="Scope & Behaviour" width="1566" height="1436" data-path="public/images/ai-2.0/connectors/metadata-ingestion/Database/database-scope-behaviour.png" />

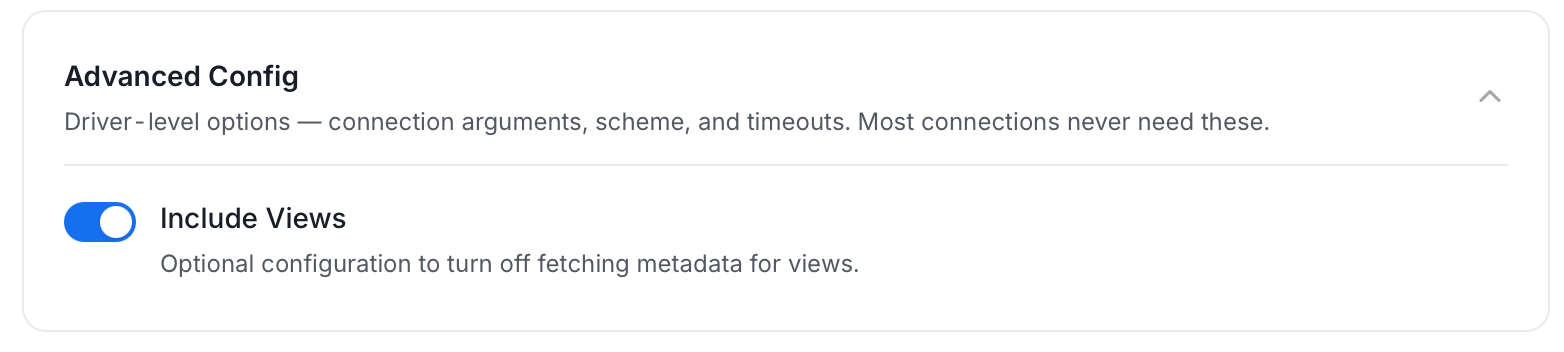
   * **Advanced Config**: Driver-level options (connection arguments, scheme, and timeouts). Most connections never need these, and they vary by connector. This section also has one ingestion-scope toggle:

     | Toggle            | Default | Description                                                                                                                                                                                                                       |
     | ----------------- | ------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
     | **Include Views** | On      | Ingest views in addition to tables. Turn off to skip views entirely. Since view lineage is derived from parsing each view's SQL definition, turning this off also stops view-based lineage from being generated for this service. |
     <img src="https://mintcdn.com/collatedocs/kTp2dTyiNAX4Np5A/public/images/ai-2.0/connectors/metadata-ingestion/Database/database-advance.png?fit=max&auto=format&n=kTp2dTyiNAX4Np5A&q=85&s=63ef86d9e746b6d31f0571b599792357" alt="Advanced Config" width="1564" height="352" data-path="public/images/ai-2.0/connectors/metadata-ingestion/Database/database-advance.png" />

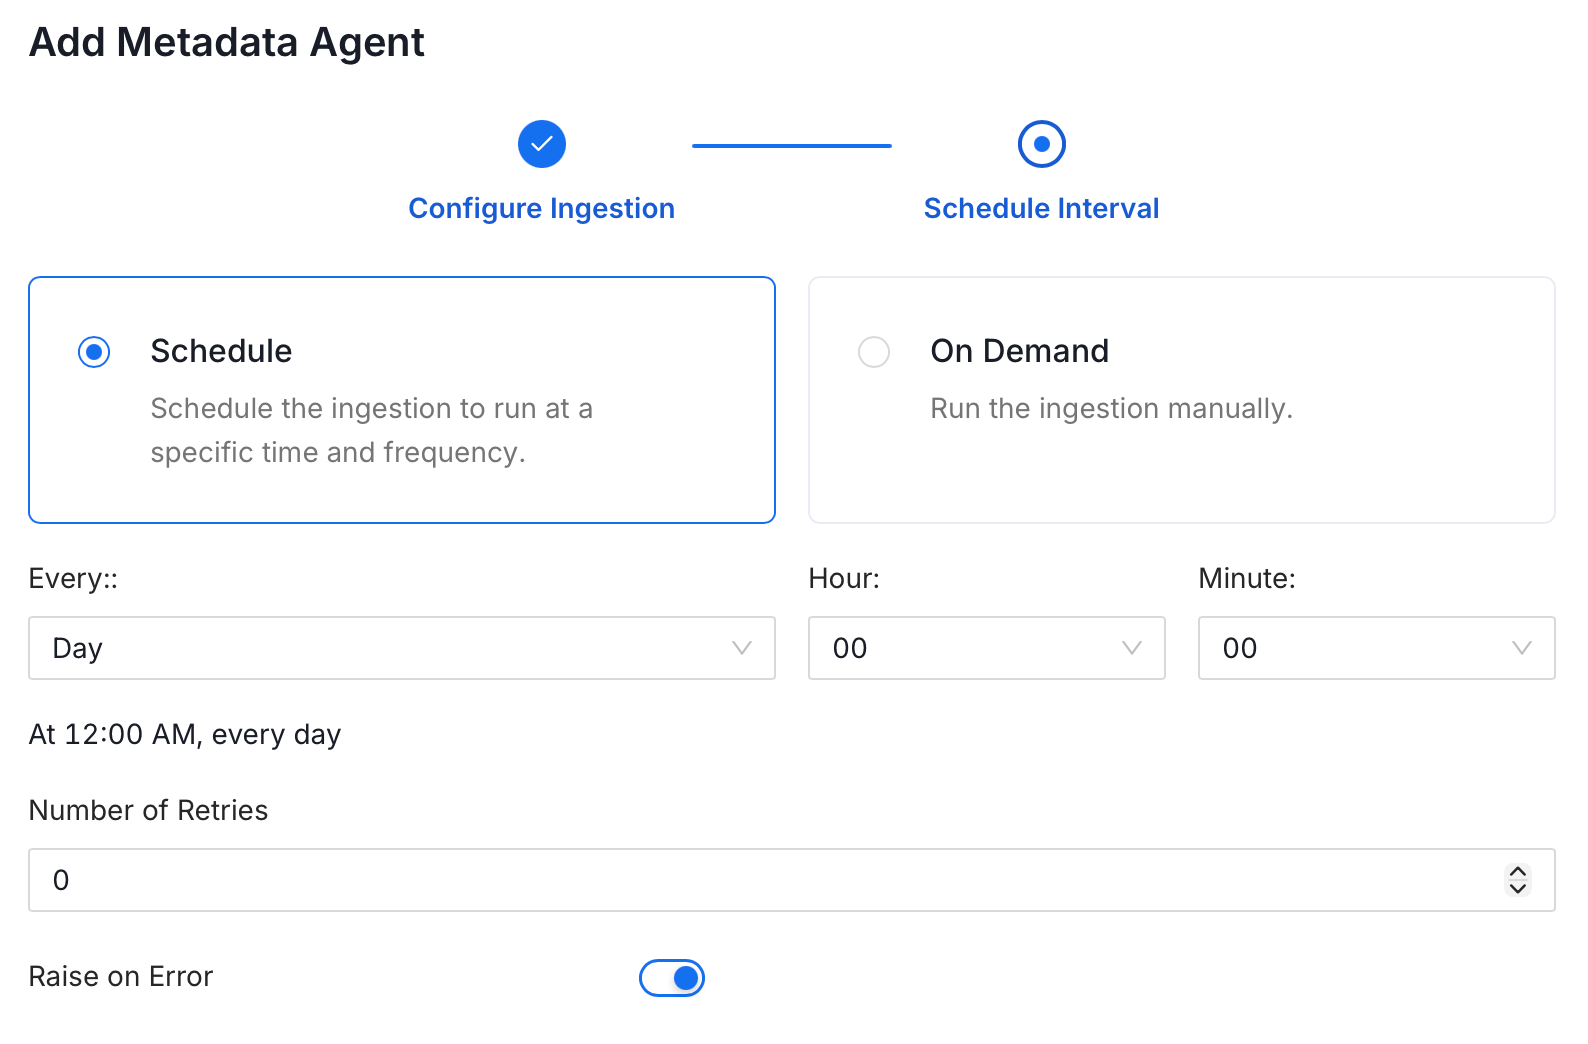
5. On the **Schedule Interval** page, set when the agent runs:

   * **Schedule**: Choose a preset interval (Hourly, Daily, Weekly, Monthly) or enter a custom cron expression.
   * **On-Demand**: No automatic schedule; trigger the agent manually when needed.
   <img src="https://mintcdn.com/collatedocs/bv5oe4uRjuorTJO1/public/images/ai-2.0/connectors/metadata-ingestion/schedule.png?fit=max&auto=format&n=bv5oe4uRjuorTJO1&q=85&s=25cc1d78f6f2a8bd115830d034d1d8d1" alt="Schedule Interval" width="1588" height="1044" data-path="public/images/ai-2.0/connectors/metadata-ingestion/schedule.png" />

6. Click **Add** to deploy the agent.

## Securing Cassandra Connection with SSL in Collate

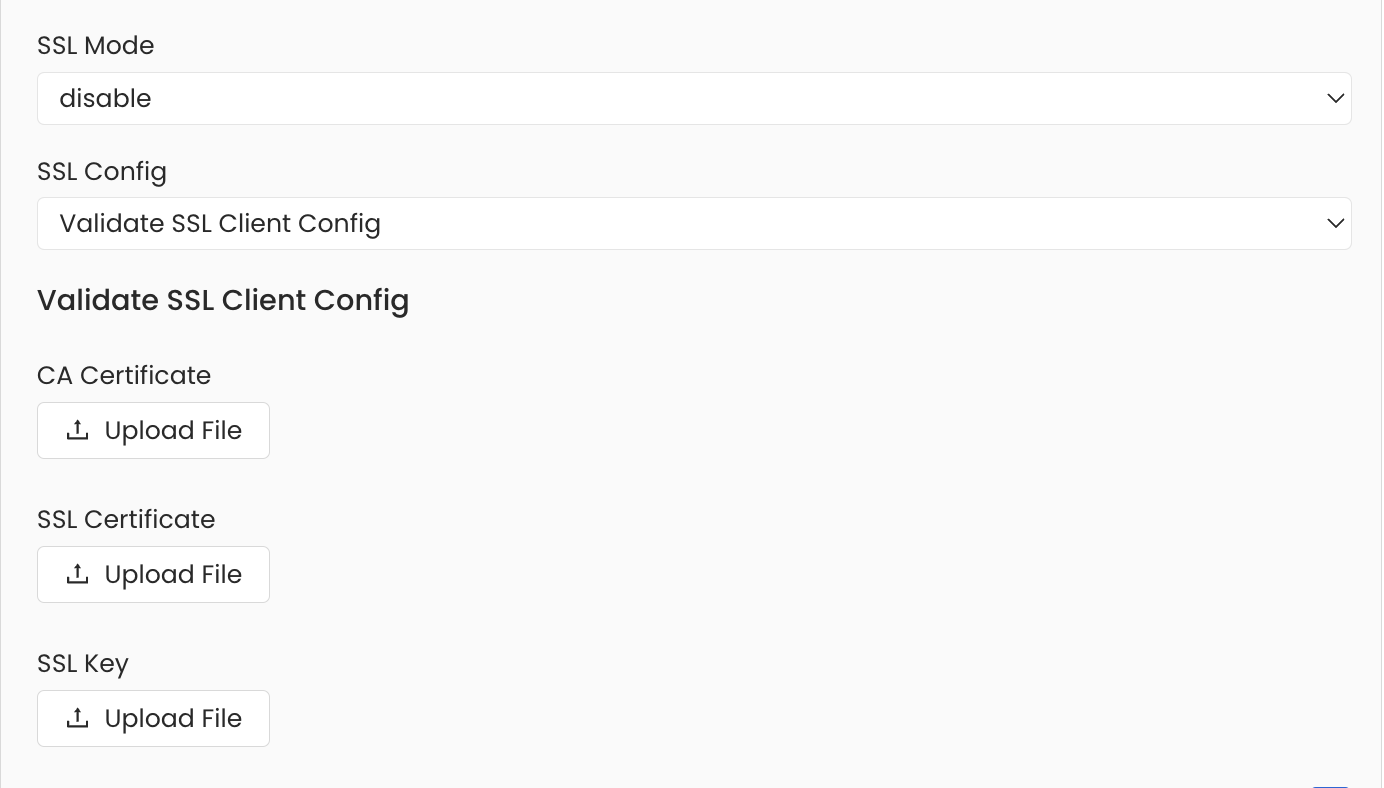
To establish secure connections between Collate and a Cassandra database, you can use any SSL mode provided by Cassandra, except disable.
Under `Advanced Config`, after selecting the SSL mode, provide the CA certificate, SSL certificate and SSL key.
<img src="https://mintcdn.com/collatedocs/qybQN_VCNOUNg9nn/public/images/connectors/ssl_connection.png?fit=max&auto=format&n=qybQN_VCNOUNg9nn&q=85&s=e90fd6e04057c3481ac6ca1987423a30" alt="SSL Configuration" height="450px" data-path="public/images/connectors/ssl_connection.png" />

## Troubleshooting

<Columns cols={2}>
  <Card title="Cassandra Troubleshooting" href="/ai-2-0/connectors/database/cassandra/troubleshooting">
    Learn more about how to troubleshoot common Cassandra connector issues and resolve configuration or ingestion errors.
  </Card>
</Columns>